
This topic describes partitions and partition types in OceanBase AI Database.
Partition introduction
You can divide the data of a regular table into different blocks according to certain rules, with data in the same block stored together physically. A table divided in this way is called a partitioned table, and each block is called a partition. The maximum number of partitions supported for a single table is controlled by the tenant-level parameter max_partition_num, with a default value of 8,192.
As shown in the following figure, a table is divided into five partitions, distributed across two servers:
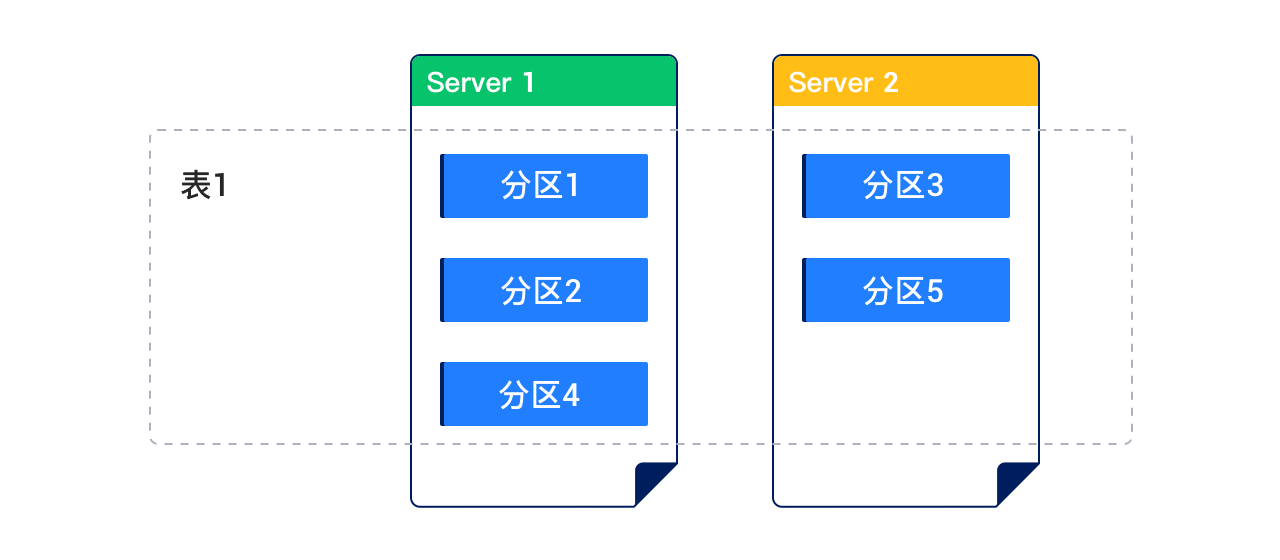
Each partition of the partitioned table shown above can be further split into multiple partitions based on certain rules. Such a table is called a subpartitioned table.
Partitioning key
The partitioning key is a set of columns used to determine which partition a data row belongs to. Its definition must follow these rules:
- If the table has a primary key, the partitioning key must be a subset of the primary key.
- If the table has a unique key but no primary key, the partitioning key must be a subset of the unique key.
- If the table has neither a primary key nor a unique key, the partitioning key can be any combination of columns, without being restricted by the primary or unique key.
Partitioning expression
A partitioning expression is a computational logic built on the partitioning key, used to map data rows to specific partitions.
Partition types
Currently supported partition types are as follows:
RANGE partitioning
RANGE COLUMNS partitioning
LIST partitioning
LIST COLUMNS partitioning
HASH partitioning
KEY partitioning
Composite partitioning
RANGE partitioning
RANGE partitioning maps data to corresponding partitions based on the range of partitioning key values established for each partition when the partitioned table is defined. It is a common partition type, often used with date types. For example, business log tables can be partitioned by day, week, or month.
In RANGE partitioning, the partitioning key must be of an integer or YEAR type. If partitioning a date field of another type, you need to use a function for conversion. The partitioning key in RANGE partitioning supports only one column.
RANGE COLUMNS partitioning
RANGE COLUMNS partitioning works similarly to RANGE partitioning, but differs in the following aspects:
The values of the partitioning key in a RANGE COLUMNS partition do not need to be integers. They can be of the following data types:
All integer types:
TINYINT,SMALLINT,MEDIUMINT,INT(INTEGER), andBIGINT.Floating-point types:
DOUBLE,FLOAT, andDECIMAL. Specifically:DECIMAL,DECIMAL[(M[,D])]DEC,NUMERIC,FIXEDFLOAT[(M,D)],FLOAT(p)DOUBLE,DOUBLE[(M,D)]DOUBLE PRECISION,REAL
Time types:
DATE,DATETIME, andTIMESTAMP.Columns of other date or time data types cannot be used as the partitioning key.
String types:
CHAR,VARCHAR,BINARY, andVARBINARY.Columns of the TEXT or BLOB data type cannot be used as the partitioning key.
You cannot use an expression as the partitioning key for a RANGE COLUMNS partition.
The partitioning key for a RANGE COLUMNS partition can include multiple columns (i.e., a column vector).
LIST partitioning
LIST partitioning allows you to explicitly control how record rows are mapped to partitions by specifying a list of discrete values for the partitioning key in each partition. This is different from RANGE partitioning and HASH partitioning. The advantage of LIST partitioning is that it facilitates partitioning unordered or unrelated datasets.
The partitioning key for LIST partitioning can be a column name or an expression. The partitioning key must be of an integer type or the YEAR type.
LIST COLUMNS partitioning
LIST COLUMNS partitioning is similar to LIST partitioning, but differs in the following aspects:
The values of the partitioning key in a LIST COLUMNS partition do not need to be integers. They can be of the following data types:
All integer types:
TINYINT,SMALLINT,MEDIUMINT,INT(INTEGER), andBIGINT.Columns of other numeric data types (for example, DECIMAL or FLOAT) cannot be used as the partitioning key.
Time types:
DATEandDATETIME.Columns of other date or time data types cannot be used as the partitioning key.
String types:
CHAR,VARCHAR,BINARY, andVARBINARY.Columns of the TEXT or BLOB data type cannot be used as the partitioning key.
You cannot use an expression as the partitioning key for a LIST COLUMNS partition.
LIST COLUMNS partitioning supports multiple partitioning keys, while LIST partitioning supports only a single partitioning key.
HASH partitioning
HASH partitioning is suitable for scenarios where RANGE or LIST partitioning methods cannot be used. It is simple to implement, distributing records into different partitions based on the hash function value of the partitioning key. HASH partitioning is a good choice if your data has the following characteristics:
You cannot identify an obvious partitioning key for the data.
Data sizes across different ranges vary greatly and are difficult to balance manually.
Data becomes heavily clustered after using RANGE partitioning.
Performance aspects such as parallel DML, partition pruning, and partition joins are critical.
In HASH partitioning, the partitioning key must be of an integer type or YEAR type, and expressions can be used.
KEY partitioning
KEY partitioning is similar to HASH partitioning. It determines which partition the data belongs to by applying a hash algorithm to the partitioning key and then performing a modulo operation on the resulting integer value.
KEY partitioning has the following characteristics:
The partitioning key in KEY partitioning is not required to be an integer; it can be of any data type except TEXT and BLOB.
Expressions cannot be used for the partitioning key in KEY partitioning.
The partitioning key in KEY partitioning supports vectors.
When no column is specified in the partitioning key, it means the primary key is used as the partitioning key.
Example:
obclient> CREATE TABLE tbl1 (col1 INT PRIMARY KEY, col2 INT)
       PARTITION BY KEY()
       PARTITIONS 5;
Query OK, 0 rows affected
Composite partitioning
Composite partitioning typically involves first using one partitioning strategy and then another within subpartitions. It is suitable when the volume of data in a business table is extremely large. Using composite partitioning allows you to leverage the advantages of multiple partitioning strategies.
Considerations for partitioning
When using an auto-increment column as the partitioning key, note the following considerations:
In OceanBase AI Database, the values of auto-increment columns are globally unique but are not guaranteed to be incremental within a partition.
Compared with other partitioning methods, insert operations on a partitioned table that uses an auto-increment column as the partitioning key may result in cross-machine transactions due to ineffective routing, which can lead to some performance degradation.
Partition naming rules
For LIST and RANGE partitions, since the partition names are specified during table creation, they are the names specified at that time.
For HASH or KEY partitions, if the partition name is not specified during creation, the system assigns a name based on the naming rules. Specifically:
When HASH or KEY partitioning is used for a partitioned table, each partition is named p0, p1, ..., pn.
When HASH or KEY partitioning is used for a subpartitioned table, each subpartition is named sp0, sp1, ..., spn.
For a template-based subpartitioned table, after subpartitions are defined, the system names them according to the ($part_name)s($subpart_name) convention. For a non-template-based subpartitioned table, the subpartition names are user-defined.
Functions allowed in partition expressions
For RANGE, LIST, and HASH partitions, the partitioning key can be an expression. Only the following functions are allowed as part of a partitioning key: