
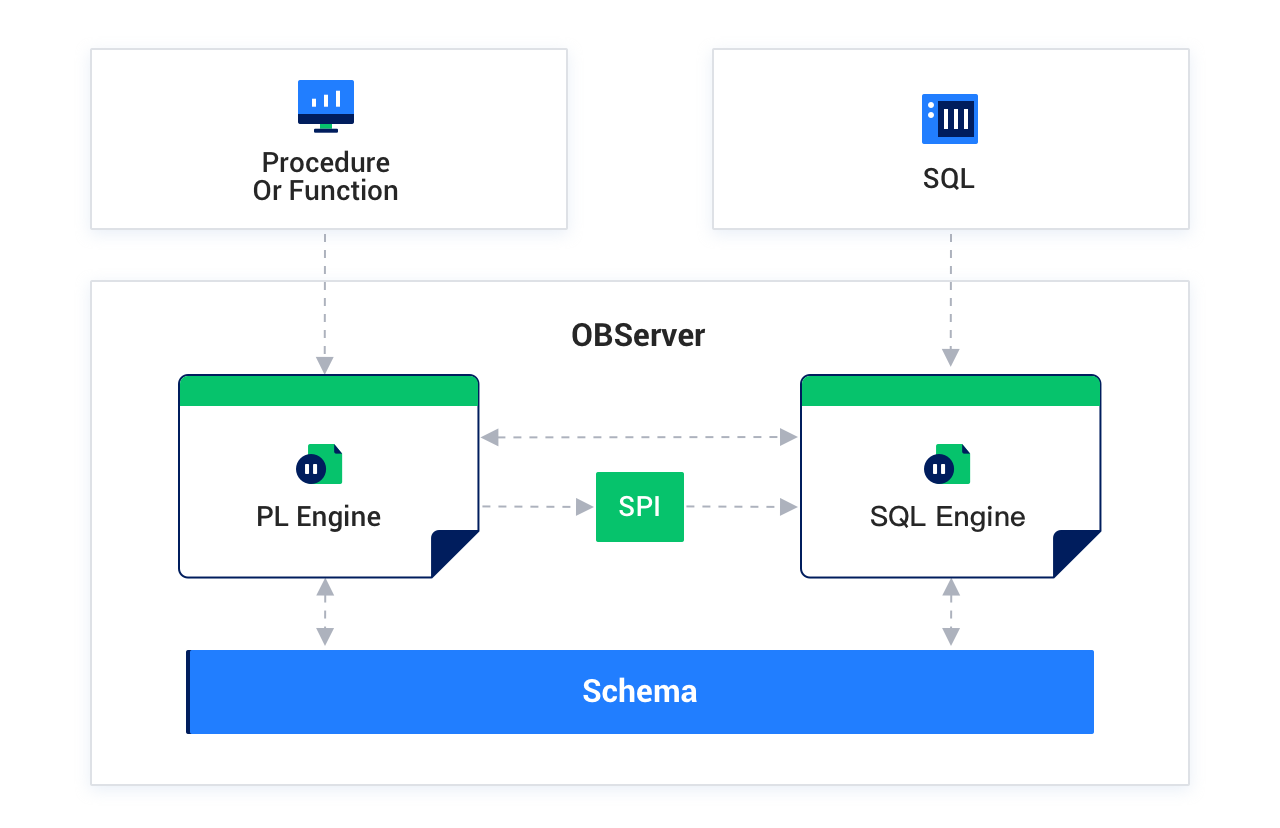
The PL engine and SQL engine can work together. SQL statements can directly access the PL engine, for example, by using user-defined functions. The PL engine can access the SQL engine through the SPI interface to perform expression evaluation and execute SQL statements.
Their interaction is illustrated in the following diagram:
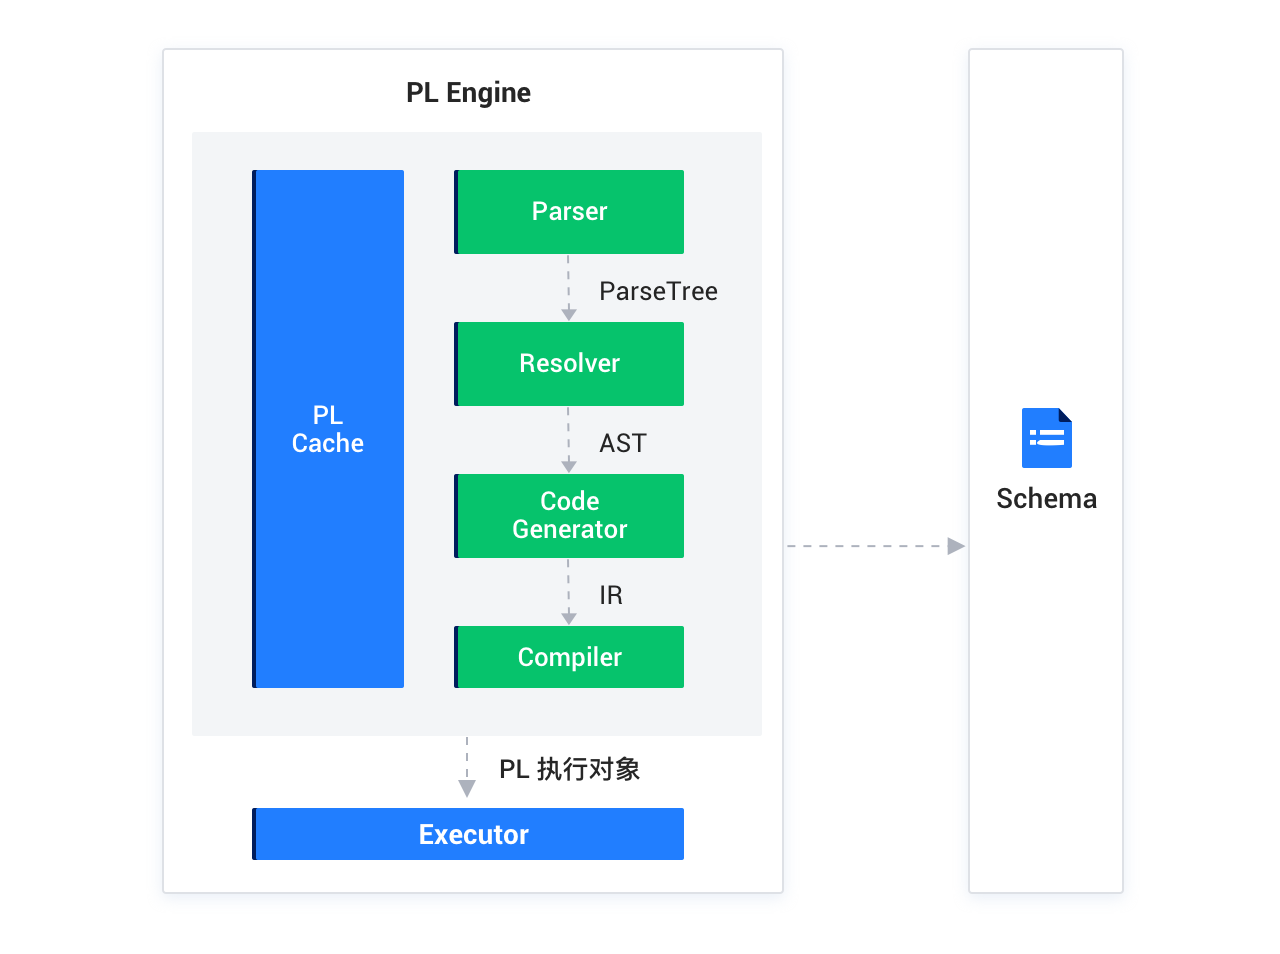
The PL Engine consists of six modules: Parser, Resolver, Code Generator, Compiler, Executor, and PL Cache. Among them, the Parser, Resolver, Code Generator, and Compiler together form a complete PL compilation process. The following figure shows this:
Parser
The parser is used to analyze PL syntax and generate a parse tree. The PL engine and SQL engine implement their own separate parsers, but both try to avoid redundant work. In an OBServer node, a query string first enters the PL parser for parsing. If it is identified as an SQL statement, it is then passed to the SQL engine for parsing.
Resolver (semantic parser)
The resolver is used for semantic analysis, such as checking variable scopes and the schemas of data objects in static SQL. It generates an abstract syntax tree (AST) for each PL statement and a global AST. The AST stores basic information about the PL definition, as well as generated global symbol tables, global label tables, global exception tables, and other information. The AST for each statement contains logical information pointing to these global tables.
Code Generator
The code generator uses the interfaces provided by LLVM to further translate the AST, converting the AST tree into intermediate representation (IR) code. The IR code can be used to verify whether the translation process is correct.
Compiler
The compiler generates machine code from IR code using just-in-time compilation (JIT) and outputs it as an executable PL object.
Executor
The executor constructs an execution environment based on the compiled PL executable object and input parameters, and invokes the function pointer to obtain the function result.
PL Cache
PL Cache is an internal mechanism of the PL Engine. The PL Engine provides a unified interface for executing procedures or functions by ID. External applications do not need to understand the PL cache mechanism; they only need to execute PL through the PL Engine. PL Cache is a hash table that looks up a value (the PL execution object) by key (the ID of the procedure or function). It also checks the validity of the PL executable object against the schema and deletes invalid ones immediately. PL Cache avoids recompiling PL every time, which improves PL execution efficiency. Therefore, there is no need to use a cache for anonymous blocks.
The PL Engine provides an external Execute interface, whose parameters include the PL ID, execution parameters params, execution context Context, and execution result Result (valid only for Functions). It first checks the PL Cache for a compiled PL executable object based on the ID. If available, it then verifies whether the Version is usable. If no PL executable object is found in the PL Cache, the compilation process is called to compile the PL. The compiled result is cached in the PL Cache and handed over to the Executor for execution. The compilation result is the memory address of a binary code segment. The Executor converts this memory address into a function pointer, passes in the execution parameters and execution context to run and obtain the result.