
DataX is an open-source version of Alibaba Cloud DataWorks Data Integration. It is an offline data synchronization tool widely used in Alibaba Group. DataX efficiently synchronizes data between heterogeneous data sources such as MySQL, Oracle, SQL Server, PostgreSQL, Hadoop Distributed File System (HDFS), Hive, ADS, HBase, Tablestore (OTS), MaxCompute (formerly known as ODPS), Hologres, Distributed Relational Database Service (DRDS), and OceanBase AI Database.
Framework design
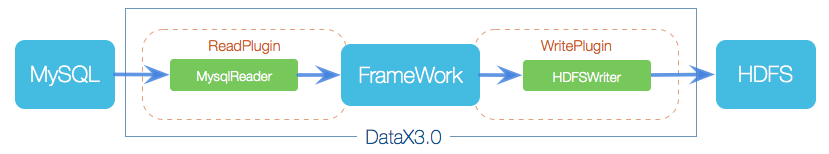
DataX is an offline data synchronization framework that is designed based on the framework + plugin architecture. It abstracts the data source reads and writes into the reader/writer plugins, which are incorporated into the entire synchronization framework.
The reader plugin is a data collection module that collects data from a data source and sends the data to the framework.
The writer plugin is a data write module that retrieves data from the framework and writes the data to the destination.
The framework builds a data transmission channel to connect the reader and the writer and processes core technical issues such as caching, throttling, concurrency, and data conversion.
DataX migrates data through tasks. Each task processes only one table and has a configuration file in the JSON format. The configuration file contains two parts: reader and writer. The reader and writer parts respectively correspond to the database read and write plugins supported by DataX. For example, when you migrate table data from a MySQL database to OceanBase AI Database, the data must be read from the MySQL database and then written to OceanBase AI Database. In this case, the txtfilereader plugin of the MySQL database and the oceanbasev10writer plugin of OceanBase AI Database are used. The following sections describe the txtfilereader and oceanbasev10writer plugins.
txtfilereader plugin
The txtfilereader plugin reads data from the local file system, converts the data, and transfers the data to the writer through DataX.
For more information about the features and parameters, see txtfilereader plugin.
oceanbasev10writer plugin
The oceanbasev10writer plugin writes data to the destination table in OceanBase AI Database. To be specific, the oceanbasev10writer plugin connects to a remote OceanBase AI Database from a Java client (MySQL JDBC or OBClient) by using OceanBase Database Proxy (ODP) and executes the corresponding INSERT statement to write the data to the remote OceanBase AI Database. The data is committed in OceanBase AI Database in batches.
oceanbasev10writer uses the DataX framework to obtain the protocol data generated by the reader and then generates an INSERT statement. If a primary key or unique key conflict occurs during data writes, a user tenant of OceanBase AI Database can update all fields in the table by using the replace mode. For performance purposes, the batch write mode is used. A write request is initiated only when the number of rows reaches the specified threshold.
DataX configuration file
The following example shows the content of the configuration file:
{
  "job": {
    "content": [
      {
        "reader": {
          "name": "streamreader",
          "parameter": {
            "sliceRecordCount": 10,
            "column": [
              {
                "type": "long",
                "value": "10"
              },
              {
                "type": "string",
                "value": "hello,hello world-DataX"
              }
            ]
          }
        },
        "writer": {
          "name": "streamwriter",
          "parameter": {
            "encoding": "UTF-8",
            "print": true
          }
        }
      }
    ],
    "setting": {
      "speed": {
        "channel": 2
       }
    }
  }
}
Notice
DataX migrates only table data. Therefore, you must create the corresponding table schema in the destination database in advance.
Place the JSON configuration file in the job directory of DataX or in a custom path. Here is a sample command:
$bin/datax.py job/stream2stream.json
The output is as follows:
<.....>

2021-08-26 11:06:09.217 [job-0] INFO  JobContainer - PerfTrace not enable!
2021-08-26 11:06:09.218 [job-0] INFO  StandAloneJobContainerCommunicator - Total 20 records, 380 bytes | Speed 38B/s, 2 records/s | Error 0 records, 0 bytes |  All Task WaitWriterTime 0.000s |  All Task WaitReaderTime 0.000s | Percentage 100.00%
2021-08-26 11:06:09.223 [job-0] INFO  JobContainer -
Task start time                    : 2021-08-26 11:05:59
Task end time                    : 2021-08-26 11:06:09
Total task duration                    :                 10s
Average task throughput                    :               38B/s
Record write speed                    :              2rec/s
Total records read                    :                  20
Total read/write failures                    :                   0
After a DataX task is executed, a simple task report is returned, providing information such as the average output traffic, write speed, and total number of read and write failures.
The settings parameter of DataX tasks can define the speed and error log tolerance.
"setting": {
            "speed": {
                "channel": 10
            },
            "errorLimit": {
                "record": 10,
                "percentage": 0.1
            }
        }
The parameters are described as follows:
errorLimitspecifies the maximum number of erroneous records allowed for the task. If this limit is exceeded, the task is interrupted and exits.channelspecifies the number of concurrent tasks. A larger number of concurrent tasks indicates higher migration performance. However, you must also consider the read stress of the source database, network transmission performance, and write performance of the destination database.
Prepare the environment
Download the .tar package from http://datax-opensource.oss-cn-hangzhou.aliyuncs.com/datax.tar.gz.
Decompress the installation package:
tar zxvf datax.tar.gz
cd datax
The directories are as follows:
$tree -L 1 --filelimit 30
.
├── bin
├── conf
├── job
├── lib
├── log
├── log_perf
├── plugin
├── script
└── tmp
The following table describes some important directories in the installation package.
Directory |
Description |
|---|---|
| bin | The directory where the executable files are located. The datax.py file in this directory is the startup script of DataX tasks. |
| conf | The directory where the log files are located. This directory stores DataX configuration files that are not related to tasks. |
| lib | The directory where the libraries that DataX depends on are located. This directory stores the global .jar files for running DataX. |
| job | This directory contains a job configuration file for testing and verifying the installation of DataX. |
| log | The log directory. This directory stores the running logs of DataX tasks. During DataX runtime, logs are output to the standard output and written to the log directory by default. |
| plugin | The plugin directory. This directory stores various data source plugins supported by DataX. |
Example
Copy the CSV file exported from the source to the destination DataX server, and then import it into the destination OceanBase AI Database.
The myjob.json configuration file is as follows:
{
    "job": {
        "setting": {
            "speed": {
                "channel": 4
            },
            "errorLimit": {
                "record": 0,
                "percentage": 0.1
            }
        },
        "content": [
            {
                "reader": {
                    "name": "txtfilereader",
                    "parameter": {
                        "path": ["/tmp/tpcc/bmsql_oorder"],
                        "fileName": "bmsql_oorder",
                        "encoding": "UTF-8",
                        "column": ["*"],
                        "dateFormat": "yyyy-MM-dd hh:mm:ss" ,
                        "nullFormat": "\\N" ,
                        "fieldDelimiter": ","
                    }
                },
                "writer": {
                    "name": "oceanbasev10writer",
                    "parameter": {
                        "obWriteMode": "insert",
                        "column": ["*"],
                        "preSql": [
                            "truncate table bmsql_oorder"
                        ],
                        "connection": [
                            {
                                "jdbcUrl": "jdbc:oceanbase://127.0.0.1:2883/tpcc?",
                                "table": [
                                    "bmsql_oorder"
                                ]
                            }
                        ],
                        "username": "tpcc",
                        "password":"********",
                        "writerThreadCount":10,
                        "batchSize": 1000,
                        "memstoreThreshold": "0.9"
                    }
                }
            }
        ]
    }
}
The parameters are described as follows:
Parameter |
Description |
|---|---|
| name | The name of the reader or writer plugin that connects to the database. The reader plugin of MySQL Database is txtfilereader, and the writer plugin of OceanBase AI Database is oceanbasev10writer. For more information about the reader and writer plugins, see DataX Data Source Guide. |
| jdbcUrl | The JDBC URL of the database to which you want to connect. The value is a JSON array and multiple URLs can be entered for a database. You must enter at least one JDBC URL in the JSON array. The value must be in compliance with the MySQL official format. You can also specify a configuration property in the URL. For more information, see Configuration Properties in the MySQL documentation.
Notice
|
| username | The username for logging on to the database.
|
| password | The password of the specified username required to log in to the database.
|
| table | The tables to be synchronized. The value is a JSON array and multiple tables can be specified at the same time. When you specify multiple tables, make sure that they use the same schema structure. The txtfilereader plugin does not verify whether the specified tables belong to the same logical table.
NoticeThe table string must be included in the
|
| column | The set of names of columns to be synchronized in the configured table. The values are specified in a JSON array. We recommend that you do not set this parameter to ['*'], because the configuration changes with the table schema. We recommend that you specify the column names instead. Column pruning is supported. You can export only the specified columns. Column reordering is supported. You can export columns without following the column order in the schema. You can specify constants in the SQL syntax format of MySQL, for example, ["id", "`table`", "1", "'bazhen.csy'", "null", "to_char(a + 1)", "2.3" , "true"].
Note
|
| where | The filter condition. The txtfilereader plugin assembles the specified column, table, and WHERE clause into an SQL statement and then extracts data based on this SQL statement. To synchronize data of the current day, you can set the condition of the WHERE clause to gmt_create > $bizdate.
NoticeYou cannot set the condition of the
|
After you configure the job file, execute the job. The syntax of the commands is as follows:
python datax.py ../job/myjob.json
More information
For more information about the open-source code of DataX, see DataX.