
Parallel execution is a strategy for optimizing SQL query tasks. It breaks down a query task into multiple subtasks, allowing them to run concurrently on multiple processors, thereby improving the overall execution efficiency of the query task.
In today's computer systems, multi-core processors, multithreading, and high-speed network connections are widely used, making parallel execution an efficient query technique. This technology significantly reduces the response time for compute-intensive large queries and is widely applied in business scenarios such as offline data warehouses, real-time reporting, and online big data analytics. It also demonstrates its powerful application capabilities in areas like batch data import and rapid index table creation.
Parallel execution significantly improves performance in the following SQL query scenarios:
- Processing large table scans, large table joins, and sorting and aggregating large volumes of data.
- Performing DDL operations on large tables, such as modifying primary keys, changing column types, and creating indexes.
- Creating tables from existing large datasets (using
Create Table As Select). - Performing batch insert, delete, and update operations.
Application scenarios
Parallel execution is not only applicable to analytical systems such as offline data warehouses, real-time reporting, and online big data analytics, but also has certain applications in the OLTP domain. It can be used to accelerate DDL operations and data batch processing tasks.
Parallel execution aims to reduce SQL execution time by fully leveraging multiple CPU and I/O resources. Serial execution is outperformed by parallel execution when the following conditions are met:
- High data access volume
- Low concurrency of SQL queries
- Low latency requirements
- Sufficient hardware resources
Parallel execution leverages multiple processors to concurrently process the same task, which can improve performance in the following system environments:
- Multiprocessor systems (SMP) and clusters
- Sufficient I/O bandwidth
- Adequate memory (for handling memory-intensive operations such as sorting and hash table construction)
- Moderate system load or load with peak-valley characteristics (e.g., system load typically below 30%)
If the system does not meet the above characteristics, parallel execution may not significantly improve performance. In some systems with high load, limited memory, or weak I/O capabilities, it may even lead to suboptimal performance.
Parallel execution does not have specific hardware requirements. However, it is important to note that the number of CPU cores, memory size, storage I/O performance, and network bandwidth all affect parallel execution performance. Any one of these factors becoming a bottleneck can impact overall performance.
How it works
Parallel execution achieves efficient concurrent execution by breaking down an SQL query task into multiple subtasks and scheduling these subtasks to run on multiple processors.
Once an SQL query is parsed into a parallel execution plan, its execution proceeds in the following steps:
- The SQL main thread (the thread responsible for receiving and parsing SQL) pre-allocates thread resources required for parallel execution based on the plan's structure. These thread resources may span clusters across multiple machines.
- The SQL main thread enables the Parallel Scheduling Operator (PX Coordinator).
- The Parallel Scheduling Operator parses the plan, breaks it down into multiple operation steps, and schedules these operations in a bottom-up order. Each operation is designed to be executed in parallel to the greatest extent possible.
- After all operations have completed parallel execution, the Parallel Scheduling Operator receives the computation results and passes them to the upper-layer operator (for example, the Aggregate operator) to serially complete the remaining non-parallel computations (such as the final SUM calculation).
Parallel granularity
The basic unit of work for parallel data scanning is called a granule.
OceanBase AI Database breaks down a table scan task into multiple units called granules, with each granule defining the scope of the scan task. Since each granule covers only the data of a single partition, the data of each partition corresponds to an independent scan task. In short, each granule corresponds to a scan task within a partition.
Based on the characteristics of granules, they can be classified into the following two types:
Partition granule
A partition granule describes the range of a complete partition. The number of partition granules created depends on how many partitions are involved in the scan task. These partitions can be either primary table partitions or index partitions. Partition granules are most commonly used in partition-wise joins to ensure that the corresponding partitions of the two tables are processed by partition granules.
Block granule
A block granule describes a continuous segment of data within a partition. In data scanning scenarios, data is typically divided using block granules. Each partition is divided into several blocks, which are connected according to certain rules to form a task queue for consumption by parallel worker threads.
The following figure illustrates how block granules work.
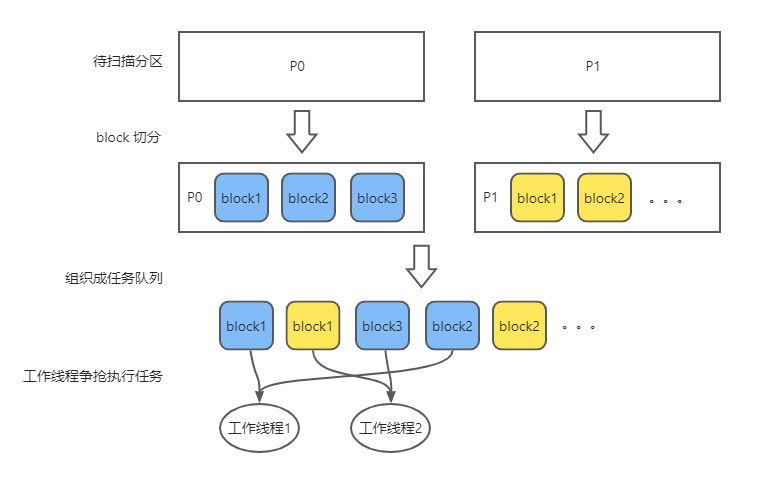
Given a specified degree of parallelism, to maintain balanced scan tasks, the optimizer automatically decides whether to divide data into partition granules or block granules. If block granules are chosen, the parallel execution framework dynamically determines block partitioning at runtime, with the overall principle being to ensure a block is neither too large nor too small. A block that is too large may lead to data skew, causing some threads to underwork; a block that is too small will result in frequent scan switch overhead.
Once the granule type (that is, block granules) is defined, each granule corresponds to a scan task. The Table Scan operator processes these scan tasks sequentially, completing them one by one until all tasks are finished.
Parallel execution model
Producer-consumer pipeline model
Parallel execution uses the producer-consumer model for pipelined execution.
After the Parallel Scheduling Operator parses a plan, it is split into multiple operation steps, each called a DFO (Data Flow Operation).
Typically, the Parallel Scheduling Operator starts two DFOs simultaneously. These two DFOs are connected in a producer-consumer manner, forming parallel execution between DFOs. Each DFO uses a set of threads for execution, which is called parallel execution within the DFO. The number of threads used by a DFO is called the DOP (degree of parallelism).
A consumer DFO from the previous stage becomes a producer DFO in the next stage. Under the coordination of the Parallel Scheduling Operator, consumer DFOs and producer DFOs start simultaneously. The following figure shows the process of DFOs in the producer-consumer model.
- Data generated by DFO A is immediately transmitted to DFO B for computation.
- After DFO B completes its computation, it stores the data in the current thread and waits for the upper-layer DFO C to start.
- When DFO B receives a notification that DFO C has started, it changes its role to producer and begins transmitting data to DFO C. Upon receiving the data, DFO C starts the computation.

In the following query example, the execution plan of the SELECT statement first performs a full table scan on the game table, then groups and sums the data by the team table, and finally calculates the total score for each team.
CREATE TABLE game (round INT PRIMARY KEY, team VARCHAR(10), score INT)
     PARTITION BY HASH(round) PARTITIONS 3;
INSERT INTO game VALUES (1, "CN", 4), (2, "CN", 5), (3, "JP", 3);
INSERT INTO game VALUES (4, "CN", 4), (5, "US", 4), (6, "JP", 4);
SELECT /*+ PARALLEL(3) */ team, SUM(score) TOTAL FROM game GROUP BY team;

obclient> EXPLAIN SELECT /*+ PARALLEL(3) */ team, SUM(score) TOTAL FROM game GROUP BY team;
+---------------------------------------------------------------------------------------------------------+
| Query Plan                                                                                              |
+---------------------------------------------------------------------------------------------------------+
| =================================================================                                       |
| |ID|OPERATOR                     |NAME    |EST.ROWS|EST.TIME(us)|                                       |
| -----------------------------------------------------------------                                       |
| |0 |PX COORDINATOR               |        |1       |4           |                                       |
| |1 | EXCHANGE OUT DISTR          |:EX10001|1       |4           |                                       |
| |2 |  HASH GROUP BY              |        |1       |4           |                                       |
| |3 |   EXCHANGE IN DISTR         |        |3       |3           |                                       |
| |4 |    EXCHANGE OUT DISTR (HASH)|:EX10000|3       |3           |                                       |
| |5 |     HASH GROUP BY           |        |3       |2           |                                       |
| |6 |      PX BLOCK ITERATOR      |        |1       |2           |                                       |
| |7 |       TABLE SCAN            |game    |1       |2           |                                       |
| =================================================================                                       |
| Outputs & filters:                                                                                      |
| -------------------------------------                                                                   |
|   0 - output([INTERNAL_FUNCTION(game.team, T_FUN_SUM(T_FUN_SUM(game.score)))]), filter(nil), rowset=256 |
|   1 - output([INTERNAL_FUNCTION(game.team, T_FUN_SUM(T_FUN_SUM(game.score)))]), filter(nil), rowset=256 |
|       dop=3                                                                                             |
|   2 - output([game.team], [T_FUN_SUM(T_FUN_SUM(game.score))]), filter(nil), rowset=256                  |
|       group([game.team]), agg_func([T_FUN_SUM(T_FUN_SUM(game.score))])                                  |
|   3 - output([game.team], [T_FUN_SUM(game.score)]), filter(nil), rowset=256                             |
|   4 - output([game.team], [T_FUN_SUM(game.score)]), filter(nil), rowset=256                             |
|       (#keys=1, [game.team]), dop=3                                                                     |
|   5 - output([game.team], [T_FUN_SUM(game.score)]), filter(nil), rowset=256                             |
|       group([game.team]), agg_func([T_FUN_SUM(game.score)])                                             |
|   6 - output([game.team], [game.score]), filter(nil), rowset=256                                        |
|   7 - output([game.team], [game.score]), filter(nil), rowset=256                                        |
|       access([game.team], [game.score]), partitions(p[0-2])                                             |
|       is_index_back=false, is_global_index=false,                                                       |
|       range_key([game.round]), range(MIN ; MAX)always true                                              |
+---------------------------------------------------------------------------------------------------------+
29 rows in set
The execution diagram for the above query example is as follows:
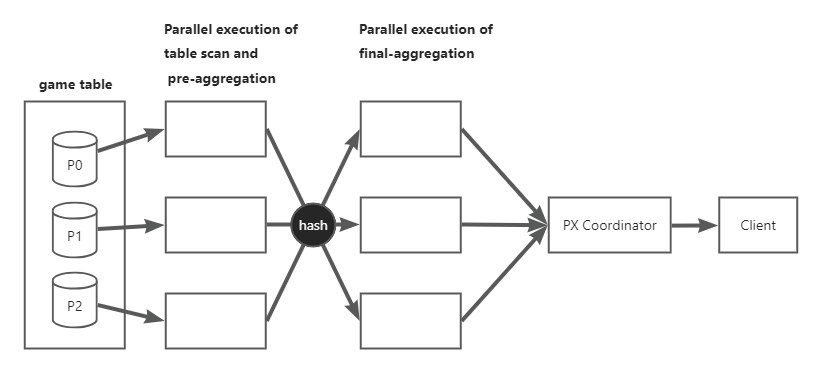
As shown in the diagram, this query actually uses six threads. The execution process and task allocation are as follows:
- Step 1: The first three threads are responsible for scanning the
gametable and pre-aggregating thegame.teamdata within each thread. - Step 2: The last three threads are responsible for the final aggregation of the pre-aggregated data.
- Step 3: The final aggregated results are handed over to the parallel scheduler, which returns them to the client.
When passing data from Step 1 to Step 2, the game.team column is used for hashing to determine which thread receives the pre-aggregated data.
Data distribution between producers and consumers
Data distribution refers to the method used when one group of parallel worker threads (producers) sends data to another group of worker threads (consumers). The optimizer employs a series of optimization strategies to select the optimal data redistribution method for best performance.
Common data distribution methods in parallel execution include:
Hash distribution
When using hash distribution, the producer computes a hash value for each data row based on the distribution key and takes the modulo to determine which consumer thread receives the data. Typically, hash distribution distributes data evenly among multiple consumer threads.
Pkey distribution
When using Pkey distribution, the producer determines the partition where the target table corresponding to the data row resides, and then sends the row data to the consumer thread that processes that partition. Pkey distribution is commonly used in partial partition-wise join scenarios, where consumer data does not need to be redistributed and can directly join with producer data on a per-partition basis, thereby reducing network traffic and improving performance.
Pkey hash distribution
When using Pkey hash distribution, the producer first determines the partition where the target table corresponding to the data row resides, then computes a hash value for the data row based on the distribution key, to decide which consumer thread processes it.
Pkey hash distribution is commonly used in parallel DML scenarios, where a single partition can be concurrently updated by multiple threads. Therefore, Pkey hash distribution is required to ensure that data rows with the same value are processed by the same thread, while data rows with different values are distributed as evenly as possible across multiple threads.
Broadcast distribution
When using broadcast distribution, the producer sends each data row to every thread at the consumer end, so that each consumer thread possesses the full dataset from the producer. Broadcast distribution is commonly used to copy data from a small table to all nodes performing a join, then execute the join locally to reduce network traffic.
Broadcast to host distribution (BC2HOST)
When using broadcast to host distribution, the producer sends each data row to each node at the consumer end, so that each consumer node possesses the full dataset from the producer. Then, consumer threads within the node collaborate to process this data.
Broadcast to host distribution is commonly used in
NESTED LOOP JOINandSHARED HASH JOINscenarios. In aNESTED LOOP JOIN, each consumer thread retrieves a portion of shared data as driving data to perform the join operation on the target table. In aSHARED HASH JOIN, each consumer thread jointly constructs a hash table based on the shared data, to avoid unnecessary overhead of each thread independently building the same hash table.Range distribution
When using range distribution, the producer divides data into ranges so that different consumer threads process different ranges of data. Range distribution is commonly used in sorting scenarios, where each consumer thread only needs to sort its assigned data to maintain order globally.
Random distribution
When using random distribution, the producer randomly scatters the data and sends it to consumer threads to ensure that each consumer thread processes approximately equal amounts of data, thereby achieving load balancing. Random distribution is often used in multi-threaded parallel
UNION ALLscenarios, where the data only needs to be scattered and balanced without any other associated constraints.Hybrid hash distribution
Hybrid hash distribution is used for adaptive join algorithms. Combining collected statistics, OceanBase AI Database provides a set of parameters to define regular values and high-frequency values. The hybrid hash distribution method distributes regular values from both sides of the join using hash distribution, high-frequency values on the left side using broadcast distribution, and high-frequency values on the right side using random distribution.

Data transfer mechanism between producers and consumers
At any given moment, two DFOs started by the parallel scheduling operator are connected in a producer-consumer manner for parallel execution. To transfer data between producers and consumers, a transmission network must be created.
For example, if producer DFO scans data with a DOP of 2, while consumer DFO performs data aggregation with a DOP of 3, then each producer thread will create three virtual links to connect to the consumer threads, resulting in a total of six virtual links, as shown in the following figure.
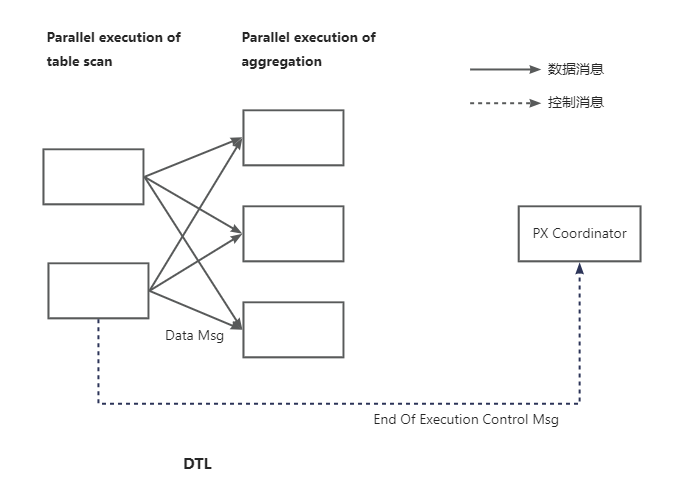
The created virtual transmission network is called the Data Transfer Layer (DTL). In the parallel execution framework of OceanBase AI Database, all control messages and row data are transmitted through the DTL. Each worker thread can establish thousands of virtual links, providing high scalability. Additionally, the DTL features data buffering, batch data sending, and automatic flow control.
When both ends of a DTL are on the same node, the DTL passes messages via memory copying. When both ends of a DTL are on different nodes, the DTL passes messages over the network.
Worker threads
In parallel queries, there are two main types of threads: one main thread and multiple parallel worker threads. The main thread shares the same thread pool as regular TP queries, while the parallel worker threads come from a dedicated thread pool.
OceanBase AI Database uses a dedicated thread pool model to allocate parallel worker threads. Each tenant has its own exclusive parallel execution thread pool on all nodes belonging to it. All parallel query worker threads are allocated through this thread pool.
Before scheduling each DFO, the parallel scheduler operator requests thread resources from the thread pool. Thread resources are immediately released after the DFO completes execution.
The initial size of the thread pool is 0 and it grows dynamically based on demand with no upper limit. To avoid excessive idle threads, the thread pool introduces an automatic recycling mechanism. For any thread:
- If it remains idle for more than 10 minutes and the number of remaining threads in the pool is greater than 8, it will be recycled and destroyed.
- If it remains idle for more than 60 minutes, it will be destroyed unconditionally.
Although the thread pool size has no upper limit, the following two mechanisms effectively enforce one in most cases:
- Before starting parallel execution, thread resources must be reserved through the Admission module. Execution can only begin after successful reservation. This mechanism limits the number of concurrent queries. For details about the Admission module, see Concurrency control and queuing.
- Each time a thread is requested from the pool, the number of threads requested at once does not exceed N. Here, N equals the
MIN_CPUvalue of the tenant's unit multiplied bypx_workers_per_cpu_quota. If exceeded, at most N threads will be allocated. The default value of the cluster parameterpx_workers_per_cpu_quotais 10. For example, if a DFO's DOP is 100, and it needs to request 30 threads from node A and 70 threads from node B, and theMIN_CPUvalue of the unit is 4 andpx_workers_per_cpu_quotais 10, then N = 4 * 10 = 40. Ultimately, this DFO actually requests 30 threads from node A and 40 threads from node B, resulting in an actual DOP of 70.
Optimize performance through load balancing
For optimal performance, the tasks assigned to all worker threads should be as equal as possible.
When SQL divides tasks using block granules, work tasks are dynamically distributed among worker threads. This minimizes workload imbalance, where no worker thread's workload significantly exceeds that of others.
When SQL divides tasks using partition granules, performance can be optimized by making the number of tasks an integer multiple of the number of worker threads. This is useful for partition-wise join and parallel DML scenarios.
Assume a table has 16 partitions, each with roughly the same amount of data. In this case, you can use 16 worker threads (with a DOP of 16) to complete the work in about one-sixteenth of the time; or use five worker threads to complete it in one-fifth of the time; or use two threads to complete it in half the time. However, if 15 threads are used to process 16 partitions, the first thread will start processing the 16th partition after finishing one. The other threads will become idle after completing their work. When the data volume per partition is similar, this configuration leads to poor performance. When the data volume per partition varies, the actual performance will vary depending on the situation.
Similarly, assume 6 threads are used to process 16 partitions, each with roughly the same amount of data.
In this case, after each thread finishes the first partition, it moves on to the second. But only four threads process the third partition, while the other two remain idle.
Generally, you cannot assume that the time required to perform parallel operations on a given number of partitions (N) and a given number of worker threads (P) equals N divided by P. This formula does not account for the fact that some threads may need to wait for others to finish the last partition. However, by selecting an appropriate DOP, workload imbalance can be minimized and performance optimized.
Scenarios where parallel execution is not recommended
Parallel execution is generally not recommended for the following scenarios:
Typical SQL execution times in the system are in the millisecond range.
Since parallel query execution itself incurs millisecond-level scheduling overhead, for short queries, the benefits brought by parallel execution may be offset by the scheduling overhead.
System load is very high.
The design goal of parallel execution is to fully utilize the system's idle resources. If the system itself has no idle resources, parallel execution may not bring additional benefits and may even affect overall system performance.
Serial execution uses a single thread to perform database operations. Serial execution is superior to parallel execution in the following situations:
- The data volume accessed by the query is very small.
- High concurrency.
- The query execution time is less than 100 milliseconds.
The following situations are not suitable for partial parallel execution:
- The topmost DFO does not require parallelism. It is responsible for interacting with the client and executing operations at the topmost level that do not require parallelism, such as
LIMITandPX COORDINATOR. - When a
TABLEUDF is involved, the DFO containing this UDF can only be executed serially, while the rest of the part can still be executed in parallel. - For regular
SELECTand DML statements in OLTP systems, parallel execution may not be applicable.