
HBase model
The HBase model differs greatly from the relational model. The following figure shows the conceptual model of HBase.
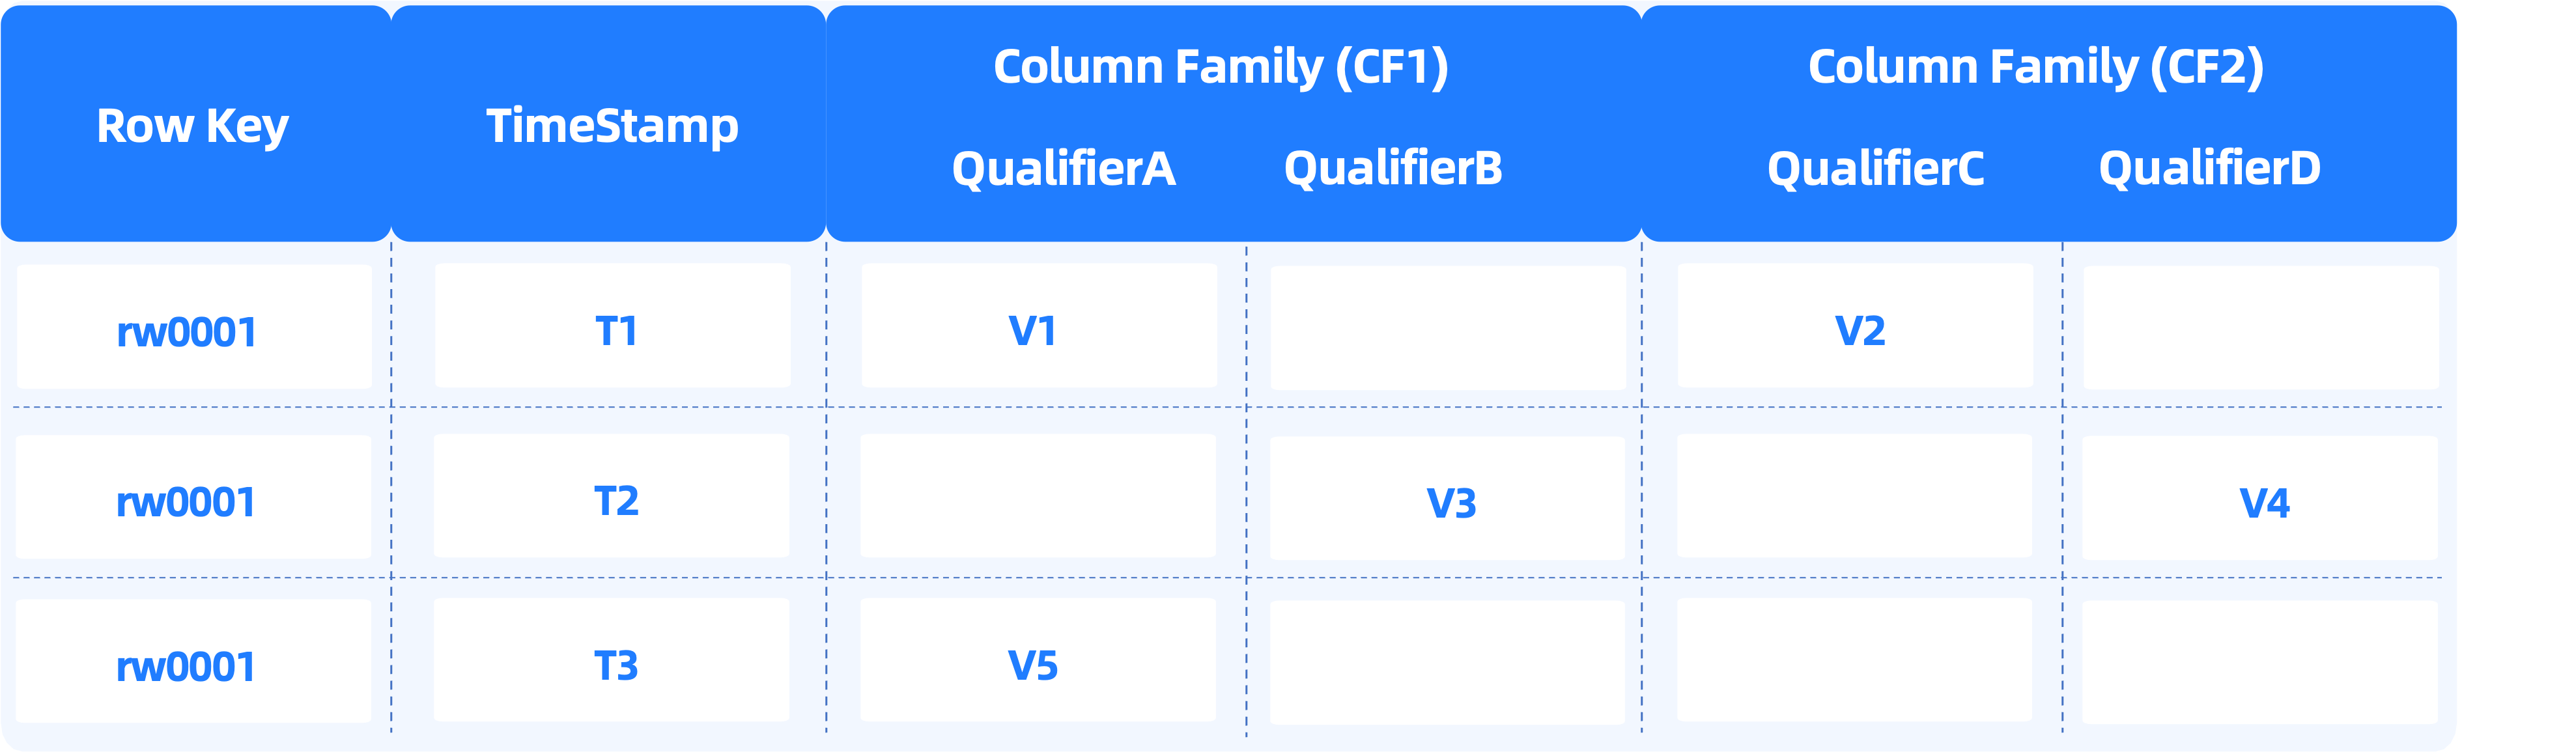
Namespace
HBase uses namespaces to logically partition tables, similar to the concept of a database in a relational database. You can create tables with the same name in different namespaces. OBKV-HBase converts namespace access into access to the corresponding database, provided that you have created that database in advance.
Table
Tables in HBase are similar to those in relational databases.
Row
A row in HBase is similar to a row in a relational database, but the two still have the following differences in the data model:
- In a relational database, a rowkey corresponds to a row of physical data, and all rows share the same schema. HBase is a schemaless database where the schemas of rows can be independent of each other.
- HBase supports multiple data versions. You can specify the data version of a row when you query data. In the following example, the K column stores the primary key of an HBase table. A row whose primary key is
defaultKey1in the HBase model is stored as five rows in OBKV. The row has four columns, and the data in thedefaultColumn3column has two versions.
+--------------+----------------+----------------+--------------+
| K            | Q              | T              | V            |
+--------------+----------------+----------------+--------------+
| defaultKey1  | defaultColumn3 | -1715698988310 | defaultValue |
| defaultKey1  | defaultColumn6 | -1715698988310 | defaultValue |
| defaultKey1  | defaultColumn9 | -1715698988310 | defaultValue |
| defaultKey1  | defaultColumn1 | -1715698965577 | defaultValue |
| defaultKey1  | defaultColumn3 | -1715698965577 | defaultValue |
+--------------+----------------+----------------+--------------+
Column family
The concept of a column family does not exist in relational databases. It is similar to the concept of vertical partitioning in some relational databases. A column family is a collection of columns whose values are physically stored together. The HBase model supports an infinitely wide table, so aggregating frequently accessed values in a column family can significantly improve performance.
Column qualifier
A relational database has a fixed schema, which means that all rows have the same number of columns and that the columns in the same position of rows are of the same data type. HBase is a schemaless database where each row can have a different number of columns and different column types. In the following example, two HBase rows are inserted into OBKV. The defaultKey1 row has three columns, and the defaultKey11 row has two columns. After the data is written to OceanBase AI Database, the corresponding data is as follows:
+--------------+----------------+----------------+--------------+
| K            | Q              | T              | V            |
+--------------+----------------+----------------+--------------+
| defaultKey1  | defaultColumn3 | -1715698988310 | defaultValue |
| defaultKey1  | defaultColumn6 | -1715698988310 | defaultValue |
| defaultKey1  | defaultColumn9 | -1715698988310 | defaultValue |
| defaultKey11 | defaultColumn1 | -1715698965577 | defaultValue |
| defaultKey11 | defaultColumn2 | -1715698965577 | defaultValue |
+--------------+----------------+----------------+--------------+
Timestamp
Each value stored in HBase has a version number, which is identified by a timestamp. You can explicitly specify a timestamp when you write data. If you do not specify a timestamp, the timestamp when the data is inserted into the storage engine is used by default.
In the following example, the T column indicates the timestamp. Considering that newly inserted data must be displayed at the top, the model layer of OBKV-HBase stores the negative value of each timestamp.
+-------------+----------------+----------------+--------------+
| K           | Q              | T              | V            |
+-------------+----------------+----------------+--------------+
| defaultKey1 | defaultColumn1 | -1715672642104 | defaultValue |
Cell
In HBase, a value of a specific version corresponds to a cell. A cell is the basic unit for storing data in HBase and consists of five components: the row key, column family, column qualifier, timestamp, and value.
Based on these five elements, each cell in HBase is uniquely identified. This means that you can accurately locate a specific cell in HBase by using this information. For example, if you know the table name, row key, column family, column qualifier, and timestamp, you can retrieve the value of that cell.
As shown in the preceding example, each row stored in OBKV-HBase corresponds to a cell in HBase.
OBKV-HBase data model
Database object types
An OBKV-HBase cluster is actually an OceanBase AI Database cluster for a user tenant.
The main database objects in OceanBase AI Database include databases, tables, views, indexes, and partitions.
After being granted the required privileges, a user can connect to a database and access or manage database objects. A database is a collection of database objects used for privilege management and namespace-based resource isolation.
The following table briefly describes the database objects in OceanBase AI Database.
For more information about each type of database object, see Overview of database objects.
Object type |
Description |
|---|---|
| Database | A collection of database objects used for privilege management and namespace-based resource isolation. |
| Table | The most basic storage unit in a database. A table is organized into rows and columns. |
| Index | An index sorts the data of one or more columns. Indexes provide fast access to specified rows in a table. For example, you can search for information about an employee by last name based on the created index. An index helps improve query efficiency. |
| Partition | OceanBase AI Database can split the data of a table into different groups based on specific rules, and data in the same group is stored in the same physical area. Such a table is called a partitioned table. OceanBase AI Database supports only horizontal partitioning, and each partition contains a subset of the data rows. Partitioning methods include HASH partitioning, RANGE partitioning, and LIST partitioning based on the mapping relationships between data and partitions. Each partition can be further divided into subpartitions from different dimensions. For example, you can partition a transaction table into several HASH partitions based on the user ID and then partition each HASH partition into several RANGE subpartitions based on the transaction time. |
| Table group | A collection of tables. It is a logical concept. By default, data is randomly distributed across tables with no direct relationship. By defining a table group, you can control the physical proximity of a group of tables in storage. |
Implementation of the OBKV-HBase data model
This section takes the following table creation statement as an example to describe the implementation of the OBKV-HBase data model.
CREATE TABLEGROUP htable1;

CREATE TABLE htable1$family1 (
  K VARBINARY(1024),
  Q VARBINARY(256),
  T BIGINT,
  V VARBINARY(1048576) NOT NULL,
  PRIMARY KEY(K, Q, T))
TABLEGROUP = htable1
PARTITION BY KEY(K) PARTITIONS 97;
OBKV-HBase uses the following mapping strategies to implement the HBase model:
- OBKV-HBase maps a table in HBase to a table group in OceanBase AI Database.
- OBKV-HBase maps a column family in HBase to a regular table in OceanBase AI Database.
Assume that HBase has a table named htable1 with a column family named family1. You need to create a table group named htable1 and a regular table named htable1$family1 in OceanBase AI Database, and bind the table to the table group. A regular table is named in the format of TableGroupName$ColumnFamilyName.
Although OBKV-HBase supports the schemaless feature of HBase, any data model implemented based on OceanBase AI Database has a schema. The preceding table creation statement defines the physical storage model of OBKV-HBase.
Where:
- `htable1` specifies the name of the OBKV-HBase table.
- `family1` specifies the name of the column family. You can use a custom name.
Note
The table name and column family name are joined by a dollar sign ($) to form the table name in OceanBase AI Database.
- The K column stores the rowkeys of the OBKV-HBase table.
- The Q column stores column qualifiers.
- The T column stores timestamps, which are the number of milliseconds elapsed since 1970-01-01 UTC.
- The V column stores values of the VARBINARY type, whose maximum length is 1 MB. If this length is insufficient, you can use the LONGBLOB type.
- The K, Q, and T columns form a composite primary key that identifies a cell in the HBase model.
- `TABLEGROUP = htable1` indicates that the table belongs to the htable1 table group.
Notice
- OBKV-HBase supports TTL at the column family level and cell level in the HBase model. For more information, see OBKV-HBase expired data deletion.
- Tables must be named in the K, Q, T, V, and TTL format (if cell-level TTL is enabled, a TTL column must be created), and the names cannot be modified afterward.
In the relational table created by using the preceding statement, data from multiple columns of a single row in the HBase table is stored in adjacent rows. Each row actually stores a cell, which is a <row, column family, column qualifier, timestamp, value> tuple, in the HBase table.
Application scenarios of the HBase model
The HBase model has more benefits than the relational model in some scenarios.
Schemaless
Schemas must be defined in conventional relational databases. Although you can change a schema after you define it, such a change may require data rebuilding in most scenarios, which can place a heavy load on the database.
HBase is a schemaless database that stores the primary key, column names, and column values. It does not require each row to have the same column definitions.
For example, a business system whose upstream is Hive usually chooses HBase to store the data generated by offline computing in Hive. The business system does not choose a relational database such as MySQL because the schema of a Hive job changes dynamically, making daily DDL operations for schema changes on MySQL impractical.
Partial update
To update data in a conventional relational database, you need to query the existing records in the database first. In other words, each update involves at least one read operation and one write operation on the database.
HBase splits one row into multiple cells for independent storage and provides an API with the semantics of PUT (overwrite). This way, you can update a single cell without the need to query data first.
For example, in a business system for financial risk control, the characteristics of some users are partially modified after big data computing every day. You can use HBase in this scenario to achieve optimal update performance because only the updated cells need to be put into HBase. As is well known, a database built on the LSM-tree architecture is write-friendly.
Wide table with sparse columns
For example, an app profiles users in many dimensions, and these dimensions may change frequently. A specific user of this app usually matches only a few profiling dimensions. If the relational model is used to describe this scenario, it is a typical case of a wide table with sparse columns. Conventional relational databases are strongly schema-oriented and cannot efficiently handle wide tables with sparse columns. For example, the database has to maintain many column values in each row and even has to maintain an empty marker for a column without a value.
HBase is suitable for wide tables with sparse columns. HBase stores only non-null columns and is not limited by a schema, which makes storage, writes, and queries highly efficient.
Multi-version
Multiple versions are very useful in some scenarios. For example, several recent login or consumption records of a user are often required in a risk control scenario. Business personnel usually need to query the multi-version data records of a specific user to assist decision-making and maintain only a certain number of data versions in the database. To achieve this in HBase, you only need to specify the data versions during the query and table creation. In a relational database, however, you need to redesign the schema, for example, add a timestamp column, to store multiple versions of data. It is a challenging task to maintain a certain number of data versions in a relational database.
TTL
HBase supports deleting expired data based on column family-level or cell-level time-to-live (TTL). It provides high resource utilization and deletion efficiency. In a relational database, you can implement TTL through an external component. However, expired data is invisible to business personnel, the impact of deleting expired data on online services is uncontrollable, and the external component consumes resources of the business system and makes the business architecture more complex.