
This topic introduces how to build an application by using a Druid connection pool, MySQL Connector/J, and OceanBase AI Database. It also covers the use of the application for fundamental database operations, including table creation, data insertion, data deletion, data updating, and data query.
 Download the druid-mysql-client sample project
Prerequisites
You have installed OceanBase AI Database and created a user tenant.
You have installed Java Development Kit (JDK) 1.8 and Maven.
You have installed Eclipse.
Note
The tool used to run the sample code in this topic is Eclipse IDE for Java Developers (2022-03), but you can also choose a tool that suits your personal preference to run the code.
Procedure
Note
The steps outlined in this topic are for the Windows environment. If you are using a different operating system or compiler, the steps may vary slightly.
- Import the
druid-mysql-clientproject into Eclipse. - Obtain the URL of OceanBase AI Database.
- Modify the database connection information in the
druid-mysql-clientproject. - Run the
druid-mysql-clientproject.
Step 1: Import the druid-mysql-client project into Eclipse
Start Eclipse and choose File > Open Projects from File System.
In the dialog box that appears, click Directory to browse and select the project, and then click Finish.
Note
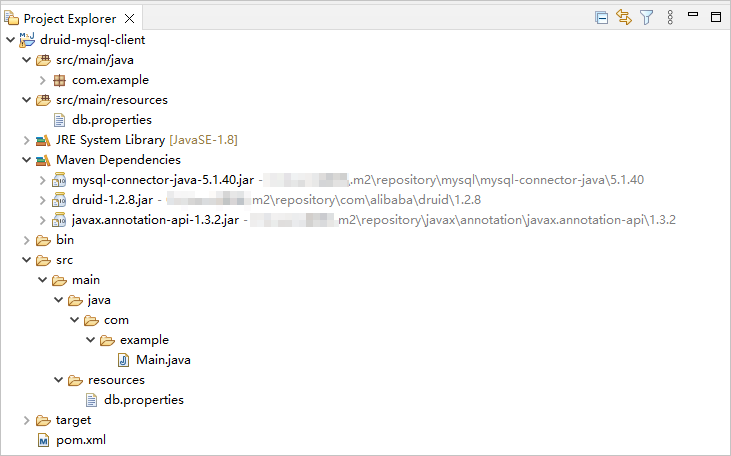
When you import a Maven project using Eclipse, it will automatically detect the
pom.xmlfile in the project, download the required dependency libraries based on the described dependencies in the file, and add them to the project.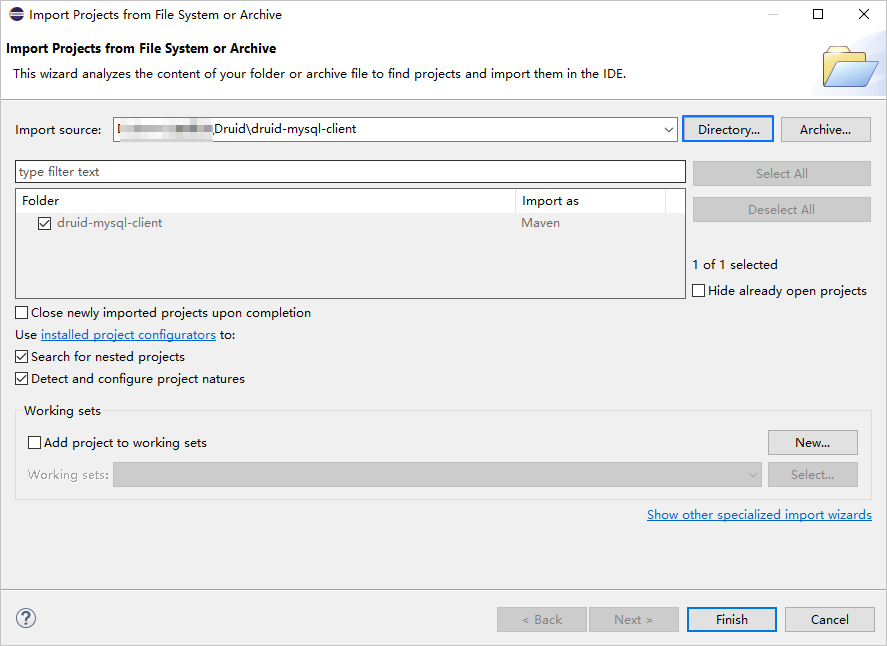
View the project.
Step 2: Obtain the URL of OceanBase AI Database
Contact the deployment personnel or administrator of OceanBase AI Database to obtain the connection string.
Here is an example:
obclient -hxxx.xxx.xxx.xxx -P2881 -utest_user001@mysql001 -p****** -DtestFor more information about the connection string, see Connect to OceanBase AI Database by using OBClient.
Fill in the URL below based on the OceanBase AI Database connection string.
jdbc:mysql://$host:$port/$database_name?user=$user_name&password=$password&useSSL=falseParameter description:
$hostspecifies the IP address for connecting to OceanBase AI Database. For connection through OceanBase Database Proxy (ODP), this parameter is the IP address of an ODP. For direct connection, this parameter is the IP address of an OBServer node.$portspecifies the port for connecting to OceanBase AI Database. For connection through ODP, the default value is2883, which can be customized when ODP is deployed. For direct connection, the default value is2881, which can be customized when OceanBase AI Database is deployed.$database_namespecifies the name of the database to be accessed.Notice
The user used to connect to the tenant must have the
CREATE,DROP,INSERT,DELETE,UPDATE, andSELECTprivileges on the database. For more information about user privileges, see Privilege types in MySQL-compatible mode.$user_namespecifies the tenant account. For connection through ODP, the tenant account can be in theusername@tenant_name#cluster_nameorcluster_name:tenant_name:usernameformat. For direct connection, the tenant account is in theusername@tenant_nameformat.$passwordspecifies the password of the account.
For more information about the connection properties of MySQL Connector/J, see Configuration Properties.
Here is an example:
jdbc:mysql://xxx.xxx.xxx.xxx:2881/test?user=test_user001@mysql001&password=******&useSSL=false
Step 3: Modify the database connection information in the druid-mysql-client project
Modify the database connection information in the druid-mysql-client/src/main/resources/db.properties file based on the information obtained in Step 2.
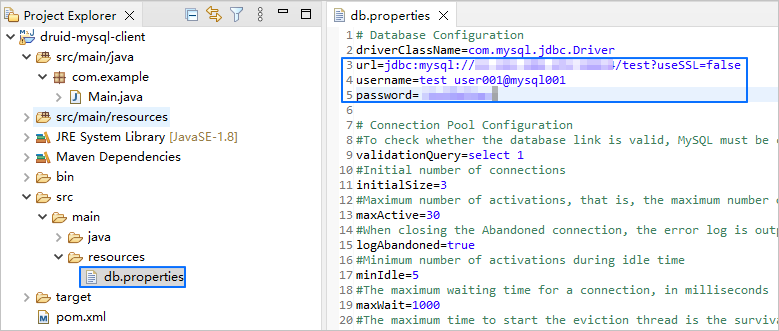
Here is an example:
- The IP address of the OBServer node is
xxx.xxx.xxx.xxx. - The port is
2881. - The name of the database to be accessed is
test. - The tenant account is
test_user001@mysql001, wheremysql001is a user tenant created in OceanBase AI Database, andtest_user001is the username of themysql001tenant. - The password is
******.
The sample code is as follows:
...
url=jdbc:mysql://xxx.xxx.xxx.xxx:2881/test?useSSL=false
username=test_user001@mysql001
password=******
...
Step 4: Run the druid-mysql-client project
In the project navigation view, locate and expand the druid-mysql-client/src/main/java directory.
Right-click the Main.java file and choose Run As > Java Application.
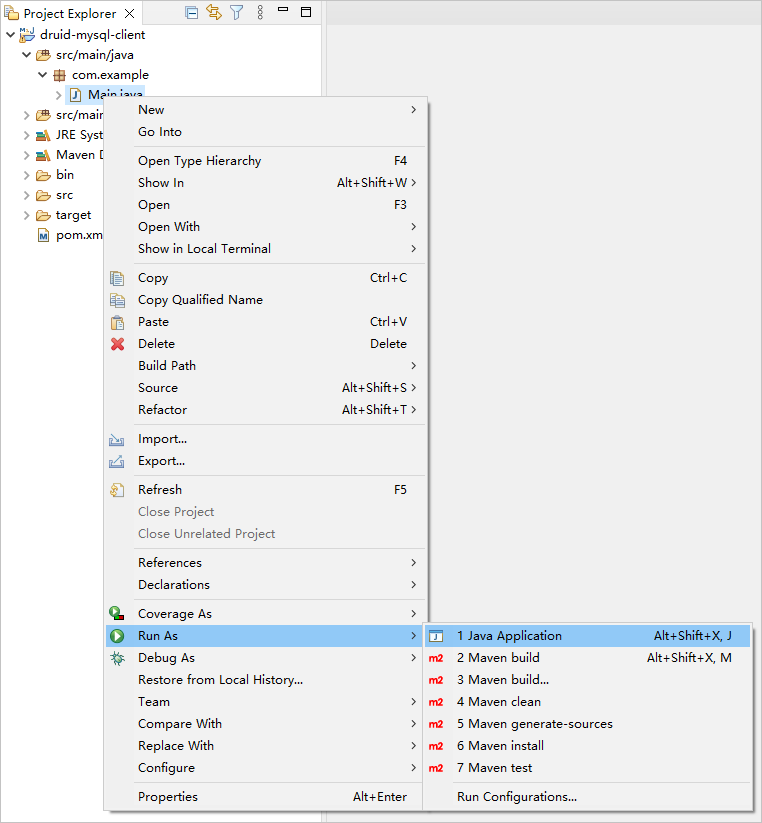
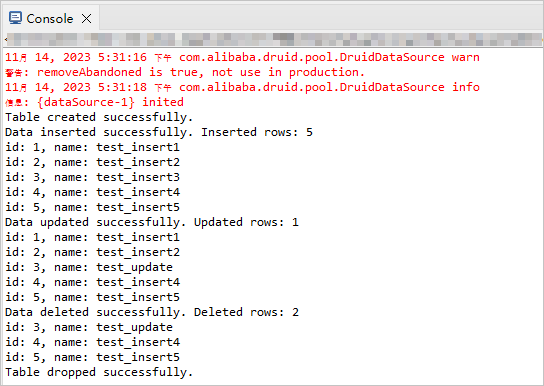
In the console window of Eclipse, view the output results.
Project code
Click druid-mysql-client to download the project code, which is a compressed file named druid-mysql-client.zip.
After decompressing it, you will get a folder named druid-mysql-client. The directory structure is as follows:
druid-mysql-client
├── src
│   └── main
│       ├── java
│       │   └── com
│       │       └── example
│       │           └── Main.java
│       └── resources
│           └── db.properties
└── pom.xml
The files and directories are described as follows:
src: The root directory for source code.main: The main code directory, containing the application's primary logic.java: The Java source code directory.com: The Java package directory.example: The package directory for the sample project.Main.java: The main class sample file, containing logic for creating tables, and inserting, deleting, updating, and querying data.resources: The resource file directory, containing configuration files.db.properties: The connection pool configuration file, containing relevant database connection parameters.pom.xml: The Maven project configuration file, used to manage project dependencies and build settings.
Code in the pom.xml file
The pom.xml file is a configuration file for Maven projects, which defines the dependencies, plug-ins, and build rules of the projects. Maven is a Java project management tool that can automatically download dependencies, compile, and package the projects.
To configure the pom.xml file, perform the following steps:
Declare the file.
Declare the file to be an XML file that uses XML standard
1.0and character encodingUTF-8.The sample code is as follows:
<?xml version="1.0" encoding="UTF-8"?>Configure the namespaces and the POM model version.
xmlns: the default XML namespace, which is set tohttp://maven.apache.org/POM/4.0.0.xmlns:xsi: the namespace for XML elements prefixed withxsi, which is set tohttp://www.w3.org/2001/XMLSchema-instance.xsi:schemaLocation: the mapping between the XML namespace and its corresponding XML schema definition (XSD) file. The value typically consists of paired strings separated by spaces. Each pair consists of a default XML namespace (http://maven.apache.org/POM/4.0.0) in the first part, and the URI of the corresponding XSD file (http://maven.apache.org/xsd/maven-4.0.0.xsd) in the second part.<modelVersion>: the POM model version used by the POM file, which is set to4.0.0.
The sample code is as follows:
<project xmlns="http://maven.apache.org/POM/4.0.0"
         xmlns:xsi="http://www.w3.org/2001/XMLSchema-instance"
         xsi:schemaLocation="http://maven.apache.org/POM/4.0.0 http://maven.apache.org/xsd/maven-4.0.0.xsd">
  <modelVersion>4.0.0</modelVersion>

 <!-- Other configurations -->

</project>
Configure basic information.
- Use
<groupId>to specify the project's organization ascom.example. - Use
<artifactId>to specify the project name asdruid-mysql-client. - Use
<version>to specify the project version as1.0-SNAPSHOT.
The sample code is as follows:
<groupId>com.example</groupId> <artifactId>druid-mysql-client</artifactId> <version>1.0-SNAPSHOT</version>- Use
Configure the properties of the project's source files.
Specifies the Maven compiler plugin as
maven-compiler-pluginand sets both the source and target Java versions to 8. This means the project's source code is written using Java 8 features, and the compiled bytecode will also be compatible with the Java 8 runtime environment. This configuration ensures the project can correctly handle Java 8 syntax and features during compilation and runtime.Note
Java 1.8 and Java 8 are different names for the same version.
The sample code is as follows:
    <build>
        <plugins>
            <plugin>
                <groupId>org.apache.maven.plugins</groupId>
                <artifactId>maven-compiler-plugin</artifactId>
                <configuration>
                    <source>8</source>
                    <target>8</target>
                </configuration>
            </plugin>
        </plugins>
    </build>
Configure the components on which the project depends.
Add the
mysql-connector-javadependency library for interacting with the database:- Use
<groupId>to specify the dependency's organization asmysql. - Use
<artifactId>to specify the dependency name asmysql-connector-java. - Use
<version>to specify the dependency version as5.1.40.
The sample code is as follows:
<dependency> <groupId>mysql</groupId> <artifactId>mysql-connector-java</artifactId> <version>5.1.40</version> </dependency>- Use
Add the
druiddependency library:- Use
<groupId>to specify the dependency's organization ascom.alibaba. - Use
<artifactId>to specify the dependency name asdruid. - Use
<version>to specify the dependency version as1.2.8.
The sample code is as follows:
<dependency> <groupId>com.alibaba</groupId> <artifactId>druid</artifactId> <version>1.2.8</version> </dependency>- Use
Code in the db.properties file
db.properties is a sample configuration file of the connection pool. The configuration file contains the URL, username, and password for connecting to the database, and other optional parameters of the connection pool.
To configure the db.properties file, perform the following steps:
Configure database connection parameters.
- Specify the class name of the database driver as
com.mysql.jdbc.Driver. - Specify the URL for connecting to the database, including the host IP address, port number, and database to be accessed.
- Specify the username for connecting to the database.
- Specify the password for connecting to the database.
The sample code is as follows:
driverClassName=com.mysql.jdbc.Driver
url=jdbc:oceanbase://$host:$port/$database_name?useSSL=false
username=$user_name
password=$password
Parameter description:
$hostspecifies the IP address for connecting to OceanBase AI Database. For connection through OceanBase Database Proxy (ODP), this parameter is the IP address of an ODP. For direct connection, this parameter is the IP address of an OBServer node.$portspecifies the port for connecting to OceanBase AI Database. For connection through ODP, the default value is2883, which can be customized when ODP is deployed. For direct connection, the default value is2881, which can be customized when OceanBase AI Database is deployed.$database_namespecifies the name of the database to be accessed.$user_namespecifies the tenant account. For connection through ODP, the tenant account can be in theusername@tenant_name#cluster_nameorcluster_name:tenant_name:usernameformat. For direct connection, the tenant account is in theusername@tenant_nameformat.$passwordspecifies the password of the account.
- Specify the class name of the database driver as
Configure other connection pool parameters.
- Specify
select 1as the SQL statement for connection verification. - Set the number of initial connections in the connection pool to 3. When the connection pool is started, three initial connections are created.
- Set the maximum number of active connections allowed in the connection pool to 30.
- Set the value of the parameter that specifies whether to record logs for abandoned connections to
true. This way, when an abandoned connection is recycled, an error log is recorded. We recommend that you set the value totruein a test environment and tofalsein an online environment to avoid compromising the performance. - Set the minimum number of idle connections in the connection pool to 5. When the number of idle connections is less than 5, the connection pool automatically creates new connections.
- Set the maximum waiting time for requesting a connection to 1,000 ms. When the application requests a connection from the connection pool, if all connections are occupied, a timeout exception is thrown when the specified waiting time expires.
- Set the minimum duration for which a connection can remain idle in the connection pool to 300,000 ms. A connection that has been idle for 300,000 ms (5 minutes) will be recycled.
- Set the value of the parameter that specifies whether to recycle abandoned connections to
true. An abandoned connection is recycled after the time specified byremoveAbandonedTimeoutelapses. - Set the timeout value of an abandoned connection to 300s. An abandoned connection that has not been used in 300s (5 minutes) will be recycled.
- Set the interval for scheduling the idle connection recycling thread to 10,000 ms. In other words, the idle connection recycling thread is scheduled every 10,000 ms (10s) to recycle idle connections.
- Set the value of the parameter that specifies whether to verify a connection when it is requested to
false. This can improve the performance. However, the obtained connection may be unavailable. - Set the value of the parameter that specifies whether to verify a connection when it is returned to the connection pool to
false. This can improve the performance. However, the connection returned to the connection pool may be unavailable. - Set the value of the parameter that specifies whether to verify idle connections to
true. When the value is set totrue, the connection pool periodically executes the statement specified byvalidationQueryto verify the availability of connections. - Set the value of the parameter that specifies whether to enable connection keepalive to
false. The valuefalsespecifies to disable connection keepalive. - Set the maximum idle period of connections to 60,000 ms. If the idle period of a connection exceeds 60,000 ms (1 minute), the connection keepalive mechanism will check the connection to ensure its availability. If any operation is performed in the connection during the idle period, the idle period is recounted.
The sample code is as follows:
validationQuery=select 1 initialSize=3 maxActive=30 logAbandoned=true minIdle=5 maxWait=1000 minEvictableIdleTimeMillis=300000 removeAbandoned=true removeAbandonedTimeout=300 timeBetweenEvictionRunsMillis=10000 testOnBorrow=false testOnReturn=false testWhileIdle=true keepAlive=false keepAliveBetweenTimeMillis=60000- Specify
Notice
The actual parameter configurations depend on the project requirements and database characteristics. We recommend that you adjust and configure the parameters based on the actual situation.
The following table describes the general Druid parameters.
Parameter |
Description |
|---|---|
| url | The URL for connecting to the database. The value contains the database type, host name, port number, and database name. |
| username | The username for connecting to the database. |
| password | The password for connecting to the database. |
| driverClassName | The name of the database driver class. If the driverClassName parameter is not explicitly configured, the Druid connection pool automatically identifies the database type (dbType) based on the URL and selects the corresponding driverClassName. This automatic identification mechanism can reduce the configuration workload and simplify the configuration process. However, if the URL cannot be correctly parsed or a nonstandard database driver class is required, the driverClassName parameter must be explicitly configured to ensure that the correct driver class is loaded. |
| initialSize | The number of connections created during the initialization of the connection pool. When the application is started, the connection pool will create the specified number of connections. |
| maxActive | The maximum number of active connections in the connection pool. When the specified value is reached, subsequent connection requests have to wait until a connection is released. |
| maxIdle | The maximum number of idle connections in the connection pool. This parameter has been deprecated. When the specified value is reached, excess connections are closed. |
| minIdle | The minimum number of idle connections in the connection pool. When the number of idle connection in the connection pool is lower than the specified value, the connection pool will create new connections. |
| maxWait | The maximum waiting time for requesting a connection, in ms. If you specify a positive value, it indicates the amount of time to wait. An exception is thrown if no connection is obtained when the specified time expires. |
| poolPreparedStatements | Specifies whether to enable the PSCache mechanism to cache PreparedStatement objects. If set to true, PreparedStatement objects will be cached to improve performance. However, the memory usage of OBProxy might continually increase. In such scenarios, configure and monitor memory usage properly to avoid memory leaks or overflow. |
| validationQuery | The SQL query statement for verifying connections. When a connection is obtained from the connection pool, this query statement is executed to verify its validity. |
| timeBetweenEvictionRunsMillis | The interval for detecting idle connections in the connection pool, in ms. A connection that has been idle for a period of time exceeding the value specified by timeBetweenEvictionRunsMillis will be closed. |
| minEvictableIdleTimeMillis | The minimum duration for which a connection can remain idle in the connection pool, in ms. A connection that has been idle for a period of time exceeding the specified value will be recycled. If you specify a negative value, idle connections will not be recycled. |
| testWhileIdle | Specifies whether to verify idle connections. If you set the value to true, the statement specified by validationQuery is executed to verify idle connections. |
| testOnBorrow | Specifies whether to verify a connection when it is obtained. If you set the value to true, the statement specified by validationQuery is executed to verify whether an obtained connection is valid. |
| testOnReturn | Specifies whether to verify a connection when it is returned to the connection pool. If you set the value to true, the statement specified by validationQuery is executed to verify a connection when it is returned to the connection pool. |
| filters | A series of predefined filters in the connection pool. These filters can be used to preprocess and postprocess connections in a specific order to provide additional features and enhance the performance of the connection pool. General filters are described as follows:
filters parameter, the connection pool applies them in the specified order. You can separate filter names with commas (,), for example, filters=stat,wall,log4j. |
Code in the Main.java file
The Main.java file is the main program of the sample application in this topic. It demonstrates how to use the data source, connection objects, and various database operation methods to interact with the database.
To configure the Main.java file, perform the following steps:
Import the required classes and interfaces.
- Declare the name of the package to which the current code belongs as
com.example. - Import the Java class
IOExceptionfor handling input/output exceptions. - Import the Java class
InputStreamfor obtaining input streams from files or other sources. - Import the Java interface
Connectionfor representing connections with the database. - Import the Java interface
ResultSetfor representing datasets of database query results. - Import the Java class
SQLExceptionfor handling SQL exceptions. - Import the Java interface
Statementfor executing SQL statements. - Import the Java interface
PreparedStatementfor representing precompiled SQL statements. - Import the Java class
Propertiesfor processing the configuration file. - Import the Java interface
DataSourcefor managing database connections. - Import the
DruidDataSourceFactoryclass of Alibaba Druid for creating Druid data sources.
The sample code is as follows:
package com.example; import java.io.IOException; import java.io.InputStream; import java.sql.Connection; import java.sql.ResultSet; import java.sql.SQLException; import java.sql.Statement; import java.sql.PreparedStatement; import java.util.Properties; import javax.sql.DataSource; import com.alibaba.druid.pool.DruidDataSourceFactory;- Declare the name of the package to which the current code belongs as
Create a
Mainclass and define themainmethod.Define a
Mainclass and amainmethod. Themainmethod demonstrates how to use a connection pool to perform a series of operations on a database. The specific steps are as follows:Define a public class named
Mainas the entry point of the program. The class name must match the file name.Define a public static method
mainas the program's entry point, which accepts command-line arguments.Use exception handling mechanisms to catch and handle potential exceptions.
Call the
loadPropertiesFilemethod to load the property file and return aPropertiesobject.Call the
createDataSource()method to create a data source object based on the configuration in the property file.Use a
try-with-resourcesstatement to obtain a database connection and automatically close it after use.- Call the
createTable()method to create a table. - Call the
insertData()method to insert data. - Call the
selectData()method to query data. - Call the
updateData()method to update data. - Call the
selectData()method again to query the updated data. - Call the
deleteData()method to delete data. - Call the
selectData()method again to query the data after deletion. - Call the
dropTable()method to drop the table.
- Call the
The sample code is as follows:
public class Main {

    public static void main(String[] args) {
        try {
            Properties properties = loadPropertiesFile();
            DataSource dataSource = createDataSource(properties);
            try (Connection conn = dataSource.getConnection()) {
                // Create table
                createTable(conn);
                // Insert data
                insertData(conn);
                // Query data
                selectData(conn);

                // Update data
                updateData(conn);
                // Query the updated data
                selectData(conn);

                // Delete data
                deleteData(conn);
                // Query the data after deletion
                selectData(conn);

                // Drop table
                dropTable(conn);
            }
        } catch (Exception e) {
            e.printStackTrace();
        }
    }

    // Define methods for retrieving and using configuration information from the property file.
    // Defines a method for obtaining a data source object.
    // Define the method for creating a table.
    // Define the method for inserting data.
    // Define a method for updating data.
    // Define a method for deleting data.
    // Define methods for querying data
    // Define a method for deleting tables.
}
Define methods for retrieving and using configuration information from the property file.
Define a private static method
loadPropertiesFile()to load the properties file and return aPropertiesobject. The specific steps are as follows:- Define a private static method
loadPropertiesFile()that returns aPropertiesobject and declares that it may throw anIOException. - Create a
Propertiesobject to store the key-value pairs from the properties file. - Use a
try-with-resourcesstatement to obtain an input streamisfor the properties filedb.propertiesthrough the class loader. - Use the
loadmethod to load the properties from the input stream into thepropertiesobject. - Return the loaded
propertiesobject.
The sample code is as follows:
private static Properties loadPropertiesFile() throws IOException { Properties properties = new Properties(); try (InputStream is = Main.class.getClassLoader().getResourceAsStream("db.properties")) { properties.load(is); } return properties; }- Define a private static method
Define a method to obtain the data source object.
Define a private static method
createDataSource()to create aDataSourceobject based on the configuration in the properties file. ThisDataSourceobject is used to manage and obtain database connections. The specific steps are as follows:- Define a private static method
createDataSource()that takes aPropertiesobject as a parameter and declares that it may throw anException. - Call the
createDataSource()method of theDruidDataSourceFactoryclass, pass in thepropertiesobject, and return aDataSourceobject.
The sample code is as follows:
private static DataSource createDataSource(Properties properties) throws Exception { return DruidDataSourceFactory.createDataSource(properties); }- Define a private static method
Define a method to create a table.
Define a private static method
createTable()to create a table in the database. The specific steps are as follows:- Define a private static method
createTable()that takes aConnectionobject as a parameter and declares that it may throw anSQLException. - Use a
try-with-resourcesstatement to create aStatementobjectstmtby calling thecreateStatement()method on the connection objectconn. - Define a string variable
sqlto store the SQL statement for creating the table. - Use the
executeUpdate()method to execute the SQL statement and create the table. - Print a success message indicating the table was created.
The sample code is as follows:
private static void createTable(Connection conn) throws SQLException { try (Statement stmt = conn.createStatement()) { String sql = "CREATE TABLE test_druid (id INT, name VARCHAR(20))"; stmt.executeUpdate(sql); System.out.println("Table created successfully."); } }- Define a private static method
Define a method to insert data.
Define a private static method
insertData()to insert data into the database. The specific steps are as follows:Define a private static method
insertData()that takes aConnectionobject as a parameter and declares that it may throw anSQLException.Define a string variable
insertDataSqlto store the SQL statement for inserting data.Define an integer variable
insertedRowswith an initial value of 0 to record the number of rows inserted.Use a
try-with-resourcesstatement to create aPreparedStatementobjectinsertDataStmtby calling theprepareStatement()method on the connection objectconnand passing in the SQL statement for inserting data.Use a
forloop to iterate five times, representing the insertion of five rows of data.- Use the
setInt()method to set the value of the first parameter to the loop variablei. - Use the
setString()method to set the value of the second parameter to the stringtest_insertplus the value of the loop variablei. - Use the
executeUpdate()method to execute the SQL statement for inserting data, and accumulate the returned number of rows affected into theinsertedRowsvariable.
- Use the
Print a success message indicating that the data was inserted, along with the total number of rows inserted.
Return the total number of rows inserted.
The sample code is as follows:
    private static int insertData(Connection conn) throws SQLException {
        String insertDataSql = "INSERT INTO test_druid (id, name) VALUES (?, ?)";
        int insertedRows = 0;
        try (PreparedStatement insertDataStmt = conn.prepareStatement(insertDataSql)) {
            for (int i = 1; i < 6; i++) {
                insertDataStmt.setInt(1, i);
                insertDataStmt.setString(2, "test_insert" + i);
                insertedRows += insertDataStmt.executeUpdate();
            }
            System.out.println("Data inserted successfully. Inserted rows: " + insertedRows);
        }
        return insertedRows;
    }
Define a method for updating data.
Define a private static method named
updateData()to update data in the database. The specific steps are as follows:- Define a private static method named
updateData(). This method takes aConnectionobject as a parameter and declares that it may throw anSQLException. - Use a
try-with-resourcesstatement to create aPreparedStatementobject namedpstmtby calling theprepareStatement()method on the connection objectconnand passing the SQL statement for updating data. - Use the
setString()method to set the value of the first parameter to the stringtest_update. - Use the
setInt()method to set the value of the second parameter to the integer value 3. - Call the
executeUpdate()method to execute the SQL statement for updating data, and assign the returned number of rows affected to theupdatedRowsvariable. - Print a success message indicating that the data was updated, along with the total number of rows updated.
The sample code is as follows:
private static void updateData(Connection conn) throws SQLException { try (PreparedStatement pstmt = conn.prepareStatement("UPDATE test_druid SET name = ? WHERE id = ?")) { pstmt.setString(1, "test_update"); pstmt.setInt(2, 3); int updatedRows = pstmt.executeUpdate(); System.out.println("Data updated successfully. Updated rows: " + updatedRows); } }- Define a private static method named
Define a method for deleting data.
Define a private static method named
deleteData()to delete data from the database. The specific steps are as follows:- Define a private static method named
deleteData(). This method takes aConnectionobject as a parameter and declares that it may throw anSQLException. - Use a
try-with-resourcesstatement to create aPreparedStatementobject namedpstmtby calling theprepareStatement()method on the connection objectconnand passing the SQL statement for deleting data. - Use the
setInt()method to set the value of the first parameter to the integer value 3. - Call the
executeUpdate()method to execute the SQL statement for deleting data, and assign the returned number of rows affected to thedeletedRowsvariable. - Print a success message indicating that the data was deleted, along with the total number of rows deleted.
The sample code is as follows:
private static void deleteData(Connection conn) throws SQLException { try (PreparedStatement pstmt = conn.prepareStatement("DELETE FROM test_druid WHERE id < ?")) { pstmt.setInt(1, 3); int deletedRows = pstmt.executeUpdate(); System.out.println("Data deleted successfully. Deleted rows: " + deletedRows); } }- Define a private static method named
Define a method for querying data.
Define a private static method named
selectData()to query data from the database. The specific steps are as follows:Define a private static method named
selectData(). This method takes aConnectionobject as a parameter and declares that it may throw anSQLException.Use a
try-with-resourcesstatement to create aStatementobject namedstmtby calling thecreateStatement()method on the connection objectconn.Define a string variable named
sqlto store the SQL statement for querying data.Call the
executeQuery()method to execute the SQL statement for querying data, and assign the returned result set to theresultSetvariable.Use a
whileloop to iterate through each row of data in the result set.- Use the
getInt()method to get the integer value of theidfield in the current row and assign it to theidvariable. - Use the
getString()method to get the string value of thenamefield in the current row and assign it to thenamevariable. - Print the values of the
idandnamefields in the current row.
- Use the
The sample code is as follows:
    private static void selectData(Connection conn) throws SQLException {
        try (Statement stmt = conn.createStatement()) {
            String sql = "SELECT * FROM test_druid";
            ResultSet resultSet = stmt.executeQuery(sql);
            while (resultSet.next()) {
                int id = resultSet.getInt("id");
                String name = resultSet.getString("name");
                System.out.println("id: " + id + ", name: " + name);
            }
        }
    }
Define a method for dropping a table.
Define a private static method named
dropTable()to drop a table from the database. The specific steps are as follows:- Define a private static method named
dropTable()that takes aConnectionobject as a parameter and declares that it may throw anSQLException. - Use a
try-with-resourcesstatement to create aStatementobject namedstmtby calling thecreateStatement()method on the connection objectconn. - Define a string variable named
sqlto store the SQL statement for dropping the table. - Use the
executeUpdate()method to execute the SQL statement for dropping the table. - Print a success message indicating that the table was dropped.
The sample code is as follows:
private static void dropTable(Connection conn) throws SQLException { try (Statement stmt = conn.createStatement()) { String sql = "DROP TABLE test_druid"; stmt.executeUpdate(sql); System.out.println("Table dropped successfully."); } }- Define a private static method named
Complete code examples
<?xml version="1.0" encoding="UTF-8"?>
<project xmlns="http://maven.apache.org/POM/4.0.0"
         xmlns:xsi="http://www.w3.org/2001/XMLSchema-instance"
         xsi:schemaLocation="http://maven.apache.org/POM/4.0.0 http://maven.apache.org/xsd/maven-4.0.0.xsd">
    <modelVersion>4.0.0</modelVersion>

    <groupId>com.example</groupId>
    <artifactId>druid-mysql-client</artifactId>
    <version>1.0-SNAPSHOT</version>
    <build>
        <plugins>
            <plugin>
                <groupId>org.apache.maven.plugins</groupId>
                <artifactId>maven-compiler-plugin</artifactId>
                <configuration>
                    <source>8</source>
                    <target>8</target>
                </configuration>
            </plugin>
        </plugins>
    </build>

    <dependencies>
        <dependency>
            <groupId>mysql</groupId>
            <artifactId>mysql-connector-java</artifactId>
            <version>5.1.40</version>
        </dependency>
        <dependency>
            <groupId>com.alibaba</groupId>
            <artifactId>druid</artifactId>
            <version>1.2.8</version>
        </dependency>
    </dependencies>
</project>
# Database Configuration
driverClassName=com.mysql.jdbc.Driver
url=jdbc:mysql://$host:$port/$database_name?useSSL=false
username=$user_name
password=$password

# Connection Pool Configuration
#To check whether the database link is valid, MySQL must be configured to select 1
validationQuery=select 1
#Initial number of connections
initialSize=3
#Maximum number of activations, that is, the maximum number of Connection pool
maxActive=30
#When closing the Abandoned connection, the error log is output. When the link is recycled, the console prints information. The test environment can add true, while the online environment is false. Will affect performance.
logAbandoned=true
#Minimum number of activations during idle time
minIdle=5
#The maximum waiting time for a connection, in milliseconds
maxWait=1000
#The maximum time to start the eviction thread is the survival time of a link (previous value: 25200000, the converted result of this time is: 2520000/1000/60/60=7 hours)
minEvictableIdleTimeMillis=300000
#Whether to recycle after exceeding the time limit
removeAbandoned=true
#Exceeding the time limit (in seconds), currently 5 minutes. If any business processing time exceeds 5 minutes, it can be adjusted appropriately.
removeAbandonedTimeout=300
# Run the idle connection collector Destroy thread every 10 seconds to detect the interval time between connections, based on the judgment of testWhileIdle
timeBetweenEvictionRunsMillis=10000
#When obtaining a link, not verifying its availability can affect performance.
testOnBorrow=false
#Check whether the link is available when returning the link to the Connection pool.
testOnReturn=false
#This configuration can be set to true, without affecting performance and ensuring security. The meaning is: Detect when applying for a connection. If the idle time is greater than timeBetweenEviceRunsMillis, execute validationQuery to check if the connection is valid.
testWhileIdle=true
#Default false, if configured as true, connection detection will be performed in the DestroyConnectionThread thread (timeBetweenEvaluation once)
keepAlive=false
#If keepAlive rule takes effect and the idle time of the connection exceeds it, the connection will only be detected
keepAliveBetweenTimeMillis=60000
package com.example;

import java.io.IOException;
import java.io.InputStream;
import java.sql.Connection;
import java.sql.ResultSet;
import java.sql.SQLException;
import java.sql.Statement;
import java.sql.PreparedStatement;
import java.util.Properties;
import javax.sql.DataSource;
import com.alibaba.druid.pool.DruidDataSourceFactory;

public class Main {

    public static void main(String[] args) {
        try {
            Properties properties = loadPropertiesFile();
            DataSource dataSource = createDataSource(properties);
            try (Connection conn = dataSource.getConnection()) {
                // Create table
                createTable(conn);
                // Insert data
                insertData(conn);
                // Query data
                selectData(conn);

                // Update data
                updateData(conn);
                // Query the updated data
                selectData(conn);

                // Delete data
                deleteData(conn);
                // Query the data after deletion
                selectData(conn);

                // Drop table
                dropTable(conn);
            }
        } catch (Exception e) {
            e.printStackTrace();
        }
    }

    private static Properties loadPropertiesFile() throws IOException {
        Properties properties = new Properties();
        try (InputStream is = Main.class.getClassLoader().getResourceAsStream("db.properties")) {
            properties.load(is);
        }
        return properties;
    }

    private static DataSource createDataSource(Properties properties) throws Exception {
        return DruidDataSourceFactory.createDataSource(properties);
    }

    private static void createTable(Connection conn) throws SQLException {
        try (Statement stmt = conn.createStatement()) {
            String sql = "CREATE TABLE test_druid (id INT, name VARCHAR(20))";
            stmt.executeUpdate(sql);
            System.out.println("Table created successfully.");
        }
    }

    private static int insertData(Connection conn) throws SQLException {
        String insertDataSql = "INSERT INTO test_druid (id, name) VALUES (?, ?)";
        int insertedRows = 0;
        try (PreparedStatement insertDataStmt = conn.prepareStatement(insertDataSql)) {
            for (int i = 1; i < 6; i++) {
                insertDataStmt.setInt(1, i);
                insertDataStmt.setString(2, "test_insert" + i);
                insertedRows += insertDataStmt.executeUpdate();
            }
            System.out.println("Data inserted successfully. Inserted rows: " + insertedRows);
        }
        return insertedRows;
    }

    private static void updateData(Connection conn) throws SQLException {
        try (PreparedStatement pstmt = conn.prepareStatement("UPDATE test_druid SET name = ? WHERE id = ?")) {
            pstmt.setString(1, "test_update");
            pstmt.setInt(2, 3);
            int updatedRows = pstmt.executeUpdate();
            System.out.println("Data updated successfully. Updated rows: " + updatedRows);
        }
    }

    private static void deleteData(Connection conn) throws SQLException {
        try (PreparedStatement pstmt = conn.prepareStatement("DELETE FROM test_druid WHERE id < ?")) {
            pstmt.setInt(1, 3);
            int deletedRows = pstmt.executeUpdate();
            System.out.println("Data deleted successfully. Deleted rows: " + deletedRows);
        }
    }

    private static void selectData(Connection conn) throws SQLException {
        try (Statement stmt = conn.createStatement()) {
            String sql = "SELECT * FROM test_druid";
            ResultSet resultSet = stmt.executeQuery(sql);
            while (resultSet.next()) {
                int id = resultSet.getInt("id");
                String name = resultSet.getString("name");
                System.out.println("id: " + id + ", name: " + name);
            }
        }
    }

    private static void dropTable(Connection conn) throws SQLException {
        try (Statement stmt = conn.createStatement()) {
            String sql = "DROP TABLE test_druid";
            stmt.executeUpdate(sql);
            System.out.println("Table dropped successfully.");
        }
    }
}
References
For more information about MySQL Connector/J, see Overview of MySQL Connector/J.